For teams shipping voice models
A small San Francisco team rooted in speech research and production voice work. We grew tired of waiting weeks for panel results.
Why we made it
TTS development means testing dozens or hundreds of training variants. Teams usually choose among them through human listening studies: recruit a panel, record sessions, gather ratings, then combine scores. The process takes 2 to 4 weeks and carries a real cost. By then, the work has moved on.
Run it whenever you save a checkpoint. It should track human MOS closely enough to flag regressions the same day they occur. Podonos is that calibrated listener model, callable from CI rather than a quarterly ritual.
Automated scores do not replace human review for final release calls. For the daily work of comparing checkpoints, though, they are the right tool.
Our method
Calibrated over approximate
Scores include confidence intervals. When a comparison falls within the CI, we state that plainly instead of suggesting an unreliable difference.
API first
Each result arrives as structured JSON under a consistent schema. Skip a dashboard and exports: connect it to your existing pipeline.
Updated every quarter
Each quarter, we refresh the listener model with new human panel data and post revised accuracy figures on the How It Works page.
Our team
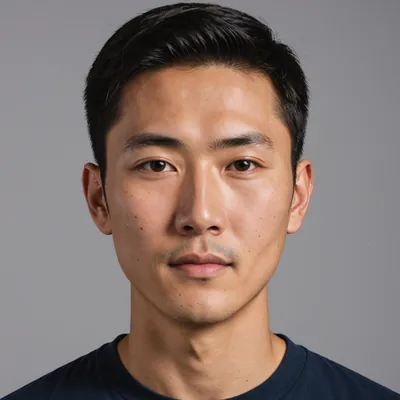
Soohyun Bae
CEO & Co-Founder
Speech perception research and TTS tools shaped the calibration method Podonos uses. Saw voice teams ship without quick quality feedback and built the methodology.
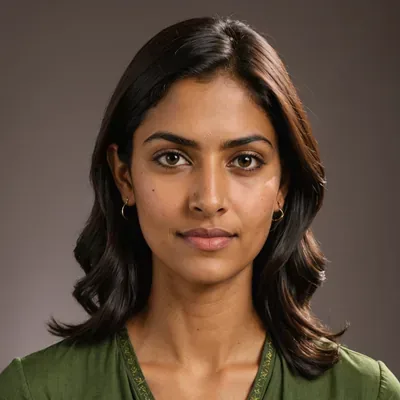
Aditi Krishnamurthy
Head of Research & Co-Founder
Led perceptual speech studies in a speech-AI research group, designing large listening panels. Runs Podonos's quarterly recalibration.
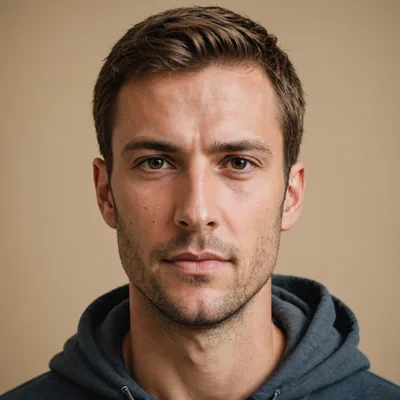
Lukas Veber
Head of Engineering
Built inference infrastructure at a real-time audio-processing startup. Owns Podonos's API, evaluation pipeline, and under 3 seconds median latency target.
Reach out
We are small and read every message. Send questions, feedback, or a note if you build in TTS and want to talk.